In short
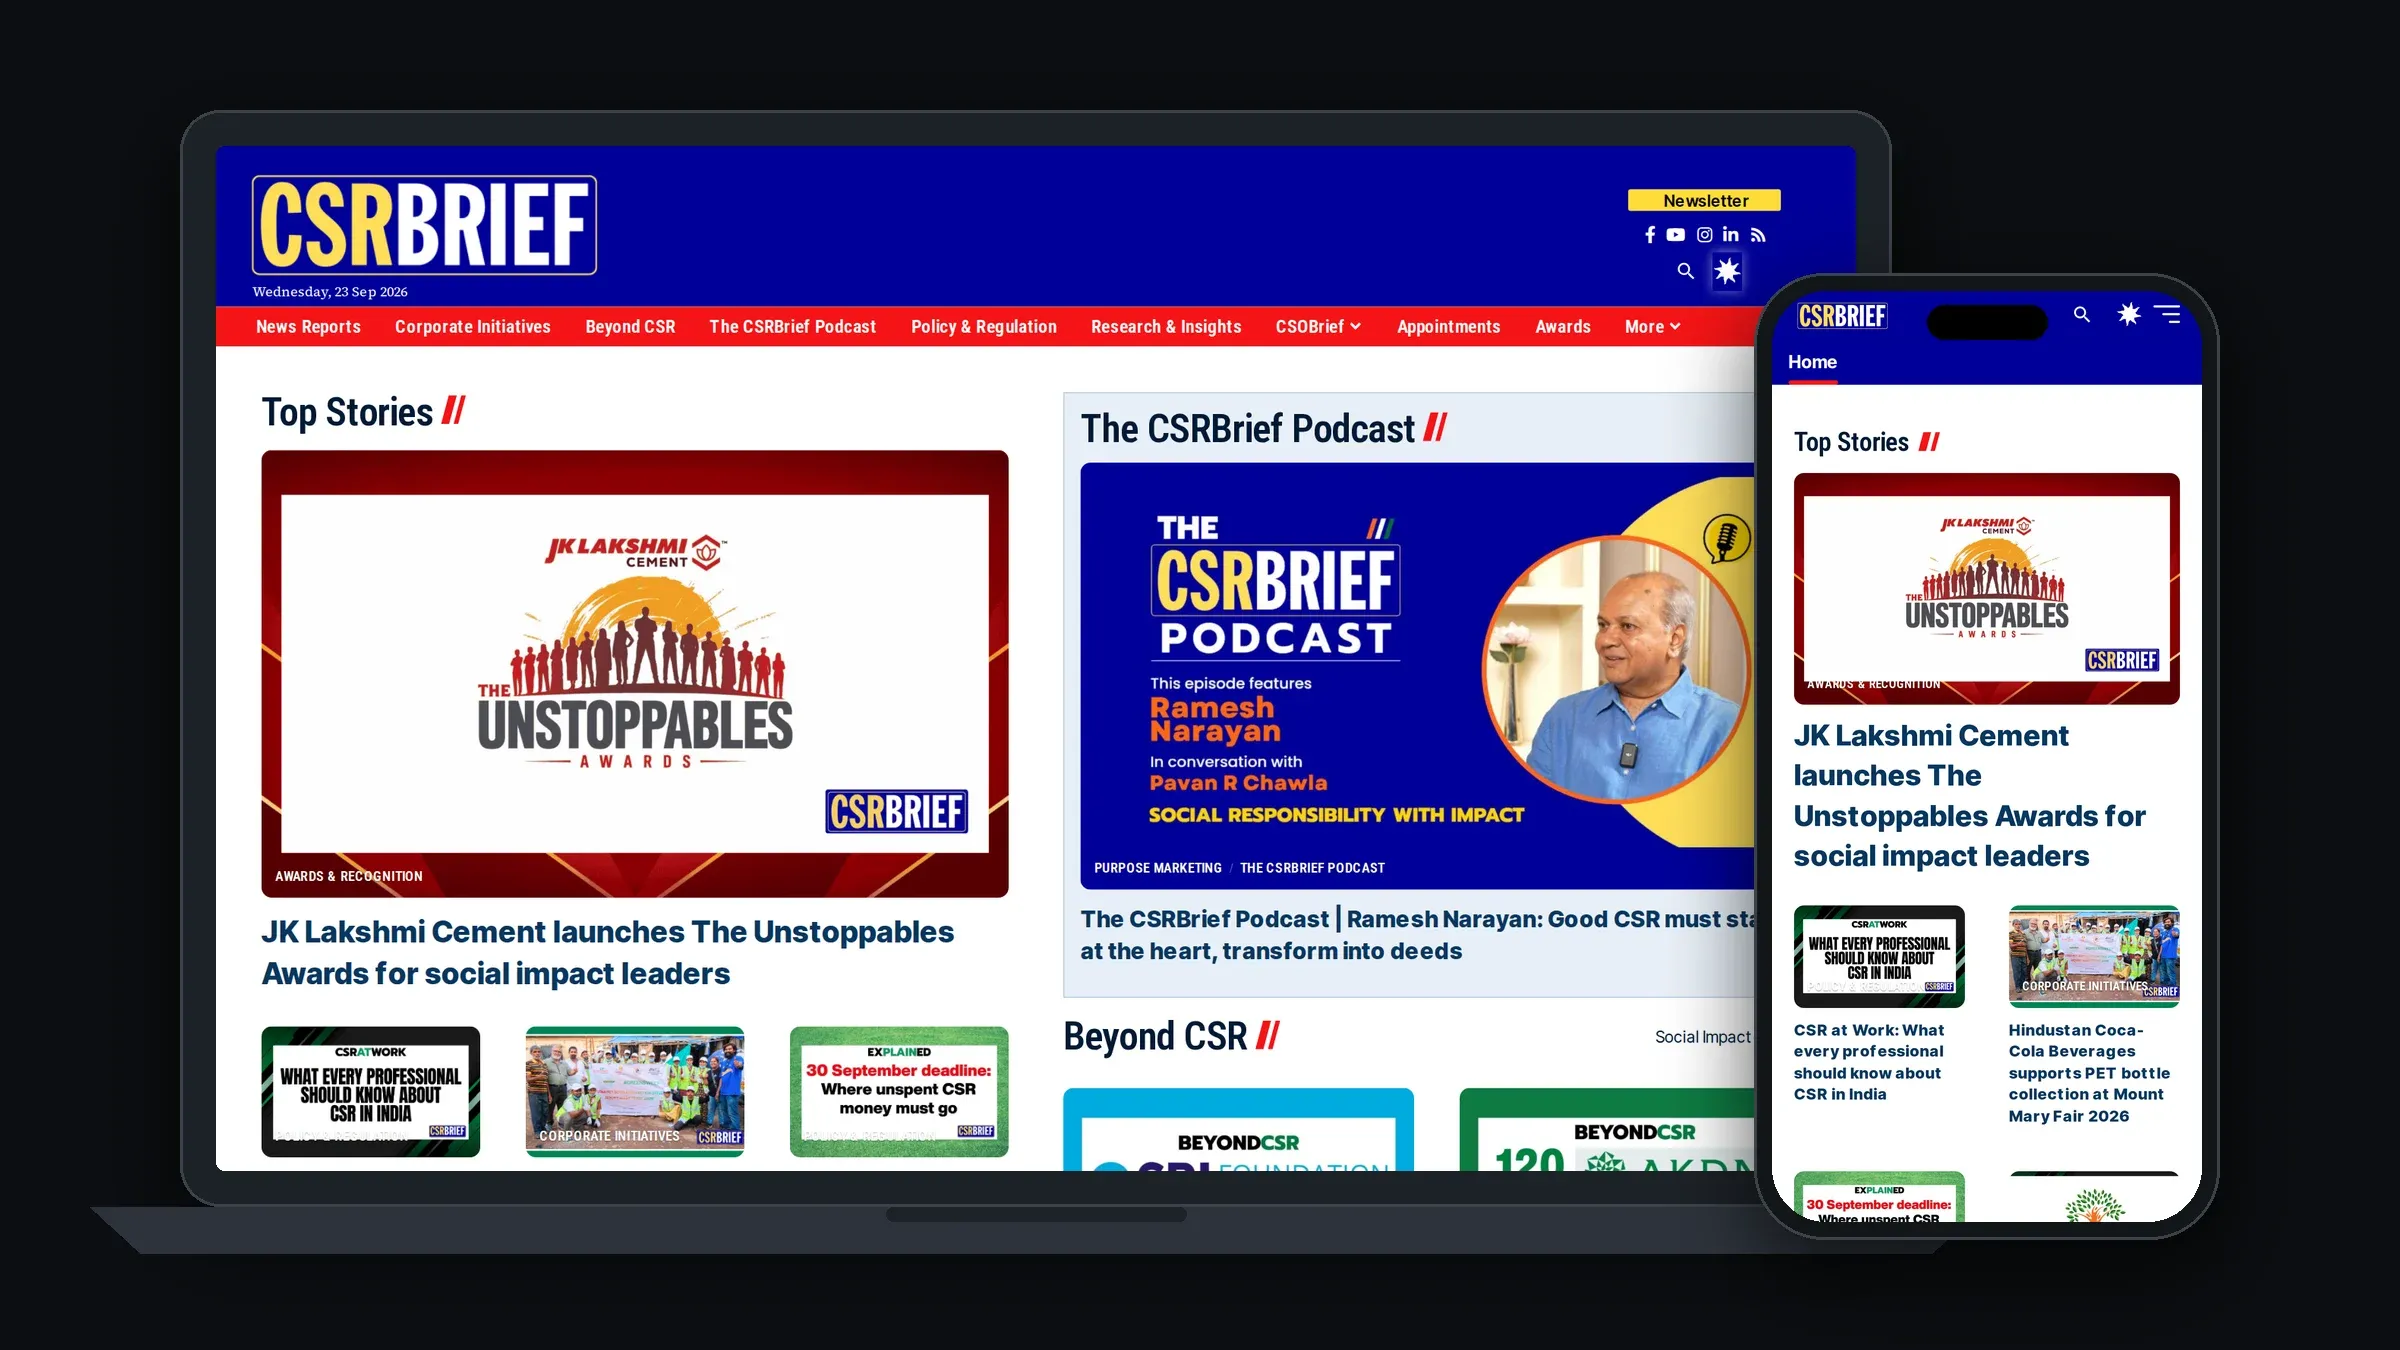
CSRBrief is an Indian news platform covering corporate social responsibility (CSR), ESG and sustainability. The editor wanted the site to be found and cited, by Google and by AI systems such as ChatGPT and Perplexity. I built a new homepage to his design, removed duplicate and incorrect SEO signals, extended the schema and took roughly 900 thin tag pages out of the sitemap. Everything is live and checked on the live site; I am still measuring the effect on indexing.
Facts at a glance
| Client | CSRBrief, published by Responsible Media Private Limited |
|---|---|
| Sector | News and media on CSR, ESG and sustainability (India) |
| Period | August 2026 to present |
| Disciplines | Web development, SEO, GEO, Strategy |
| Stack | WordPress, Foxiz, Elementor, All in One SEO Pro, Cloudflare, Search Console, GA4 |
| Status | Live, ongoing |
About the client
CSRBrief publishes daily news on corporate initiatives, policy, research and opinion, along with its own podcast. The site is young and has an older sister title at the same publisher. The newsroom publishes several articles a day, so everything I build has to fill itself without manual work.
The brief
The editor wanted a new homepage based on his own design, and a site that is technically ready to be found and cited. His position was clear: being found and cited matters more than keeping content behind walls. That guided every decision about crawlers, robots.txt and llms.txt (a file that gives AI systems an overview of the site).
Starting point
I began with a baseline of six key pages: status code, canonical, schema, title and load time. What I found:
- The theme had its own SEO module running next to the SEO plugin. Every page carried two meta descriptions, one with demo text.
- Author, tag and date archives showed zero articles. They pointed to a template that no longer existed.
- The sitemap offered about 1,100 URLs, roughly 85 percent of them tag pages with one or two articles that were set to noindex (keep out of Google).
What I did
The homepage
I built the homepage with a script rather than by hand. If something breaks, I can rebuild it instead of restoring forty blocks one by one. Every block fills itself from a category or tag, so the newsroom has nothing to maintain. I followed the client’s design down to heading sizes and colours, and made sure every block stays readable in the theme’s dark mode.
Technical SEO and indexing
I switched off the theme’s duplicate SEO features. I restored the empty archives and set thin archives (fewer than three articles) to noindex automatically. I removed tags from the sitemap and from llms.txt. Deliberately not done: deleting categories. That would have needed redirects, and the newsroom fills them anyway.
Schema for search engines and AI
I extended the existing schema instead of adding a second block next to it. Two blocks describing the same page leave Google to choose. New additions include: podcast schema that picks up every new episode by itself, full author data for all authors, a ContactPage that separates editorial and commercial contacts, and the Article type instead of NewsArticle for the evergreen Beyond CSR series.
Analytics and email
I placed GA4 once, without an extra plugin. The client updated the DNS for email authentication (proof that mail really comes from the domain) himself. I checked every step in public DNS.
How I checked it
I always measure on the live page, logged out, after clearing the site cache and Cloudflare. In the editor, something can look saved when it is not.
- At the homepage switch, I compared title and meta description with the baseline. Straight after, the page name showed up as the title in the source. You would never spot that by eye. Fixed, and then identical to the baseline word for word.
- I measured the homepage, an article and the author page at 390, 940 and 1440 pixels wide: no horizontal scrolling.
- In dark mode I measured contrast per block. At first, 25 spots sat at 1.1 to 1, which is unreadable. After the fix: none below 3 to 1.
- After each schema change I also checked pages that should not change. After the Article rule for Beyond CSR, three regular news stories stayed NewsArticle.
- A first attempt to clean the sitemap with code also removed the articles, from 143 to 1. I saw it straight away in the count, rolled it back and used the setting in the SEO plugin instead.
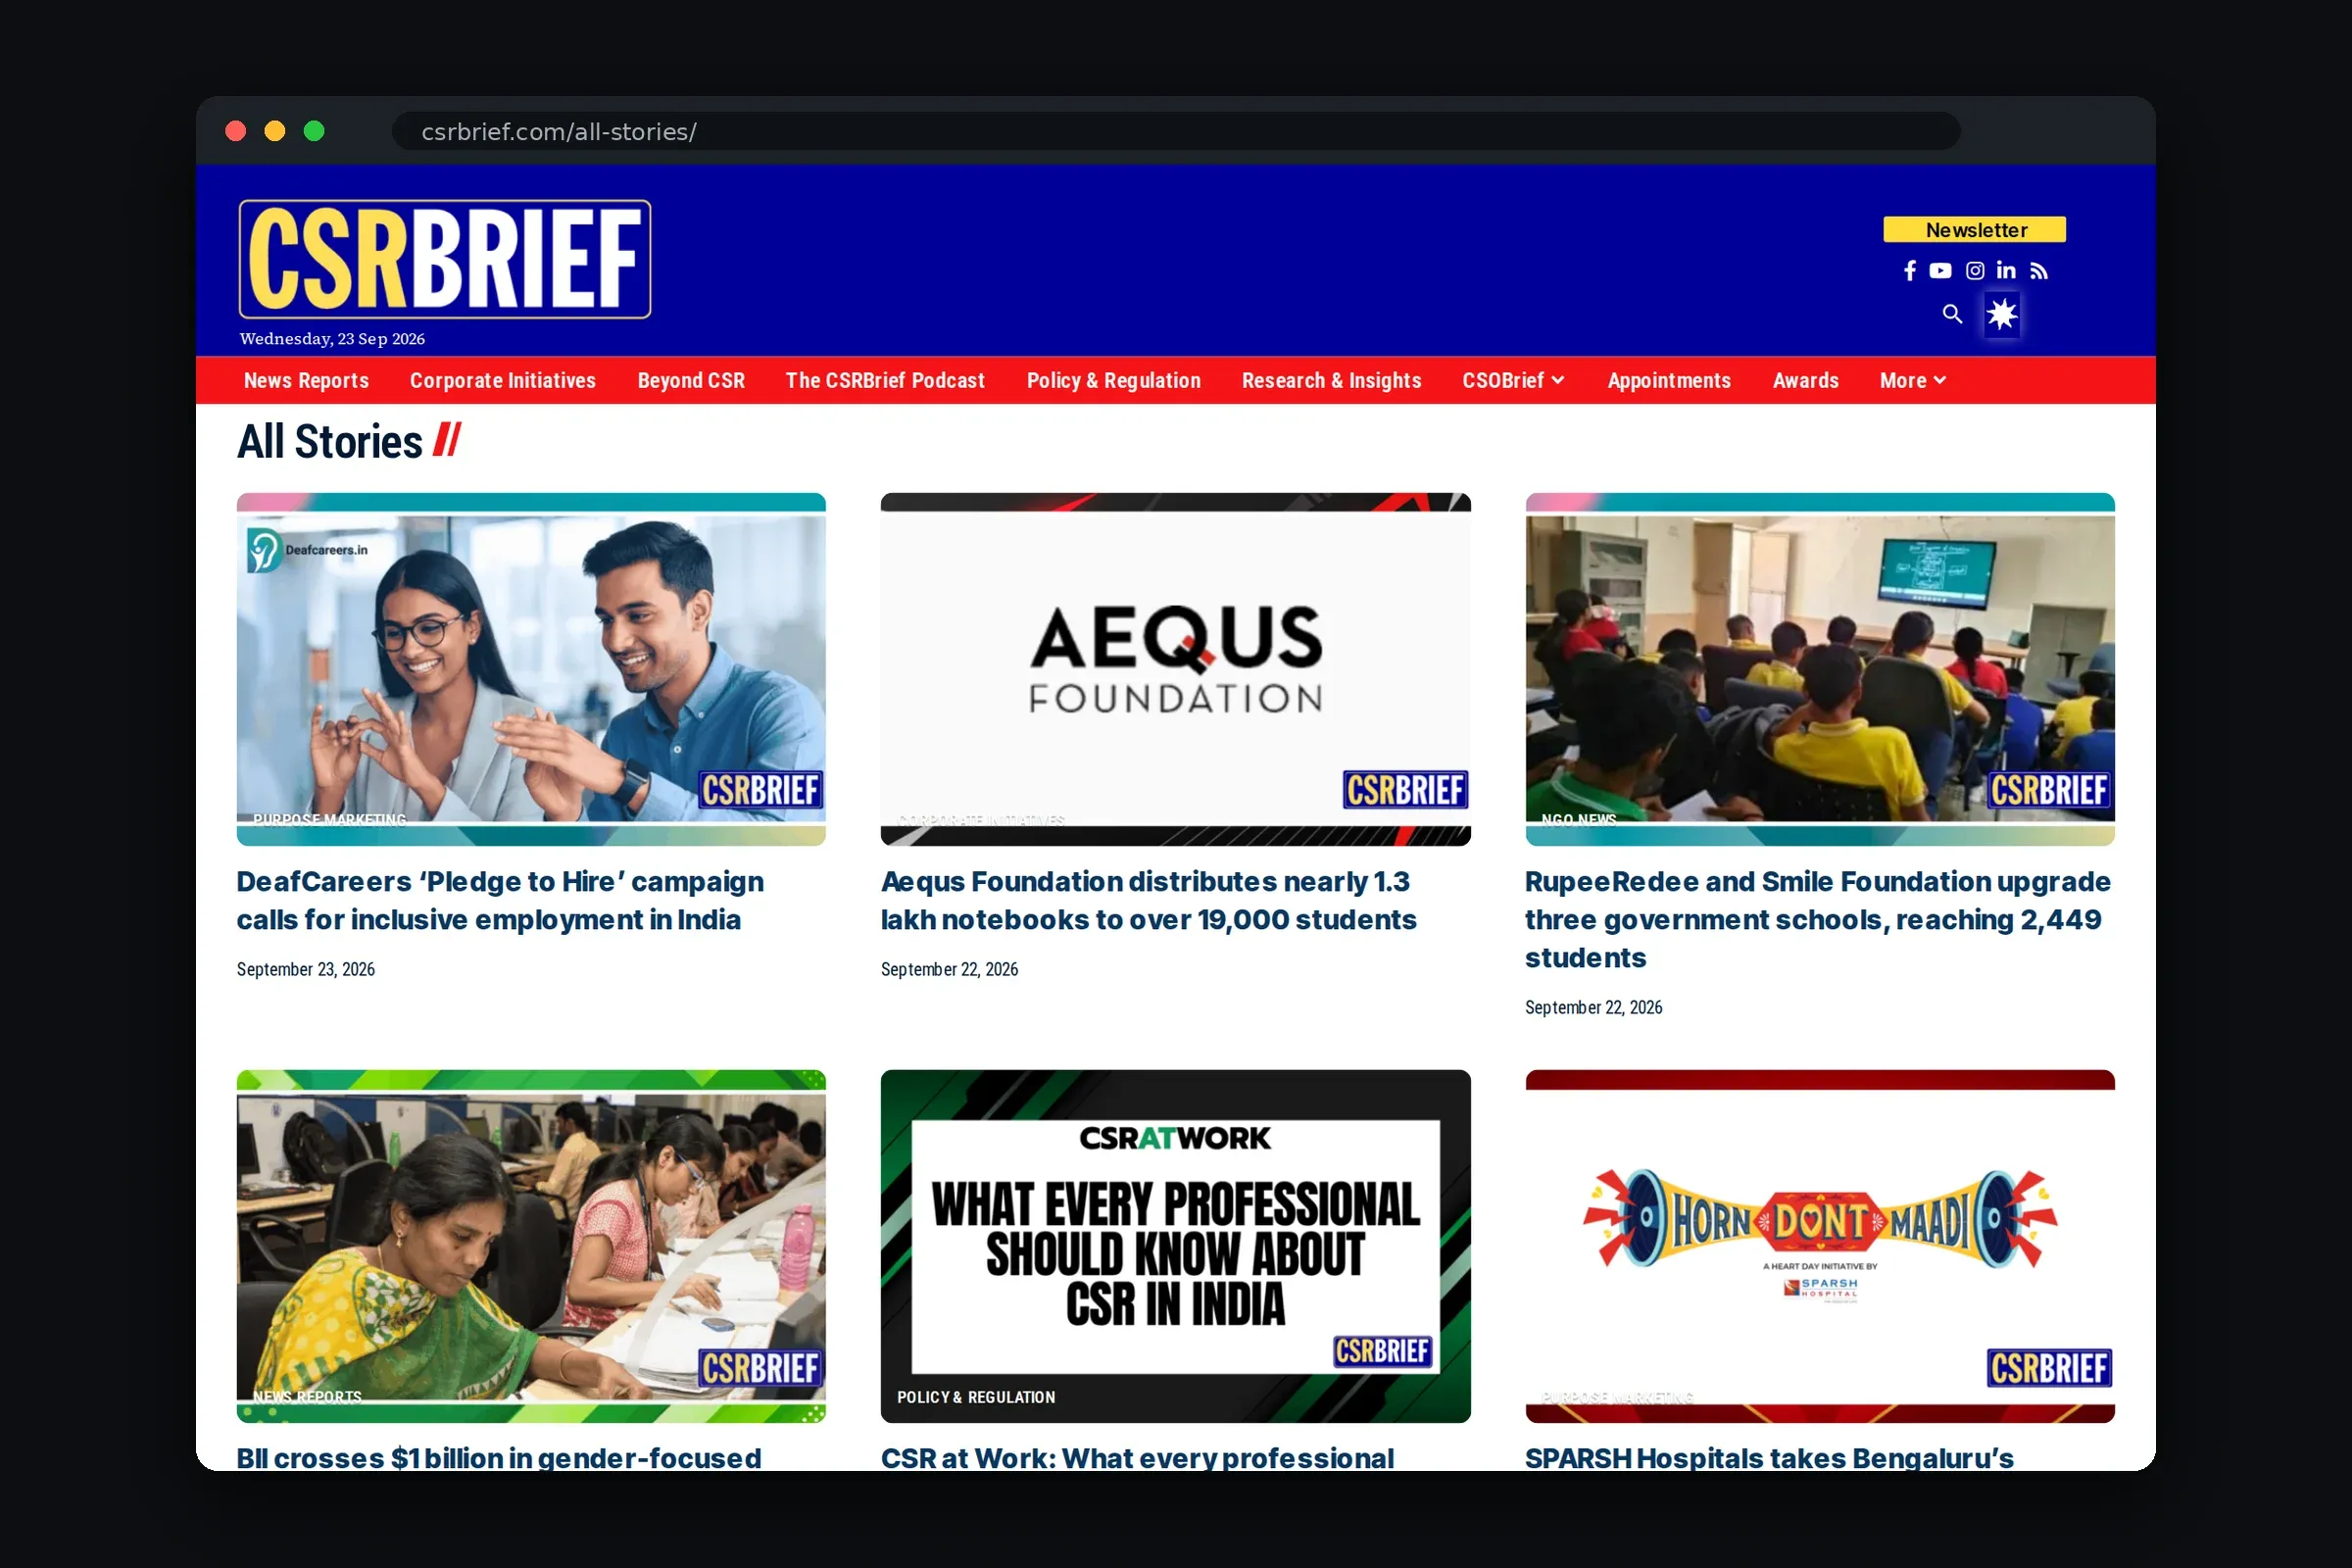
- For the All Stories archive page I compared every reachable article with the sitemap: 150 of 150, none missing.
Results
There are no measured search results to report yet. On 9 September 2026, Search Console showed that most of the site was not yet indexed. Measured on the live site:
- Sitemap down from about 1,100 to 183 URLs (9 September 2026).
- llms.txt down from 110,904 to 50,241 bytes, with no tag entries (9 September 2026).
- One meta description and one schema block per page, where there used to be two or three (27 August 2026).
- Author, tag and date archives up from zero to ten or more articles per page (25 August 2026).
What the client says
Got yet another project done by Julian, and I’m beginning to sound like a stuck record - he is the best. Only the unfortunate will pass him over. Julian is peerless. Just nobody like him in his space on the freelance professionals universe. Thank you Julian.
These reviews were posted by verified clients on Fiverr. View them on my Fiverr profile. See all reviews on Fiverr
What comes next
I am tracking in Search Console whether indexing moves now that the sitemap is clean. For the evergreen series I have proposed tables, sources and internal links, so AI systems can cite them more easily.
Frequently asked questions
My articles are in the sitemap but not in Google. Where do I start?
First look at what else the sitemap offers. At CSRBrief, about 85 percent of the URLs were noindex pages. Remove them through the SEO plugin.
Should I allow AI crawlers separately in robots.txt?
Not if nothing is blocked, as was the case at CSRBrief. A separate rule for one crawler can even backfire: that crawler then ignores the general rules.